Relay
(2026)
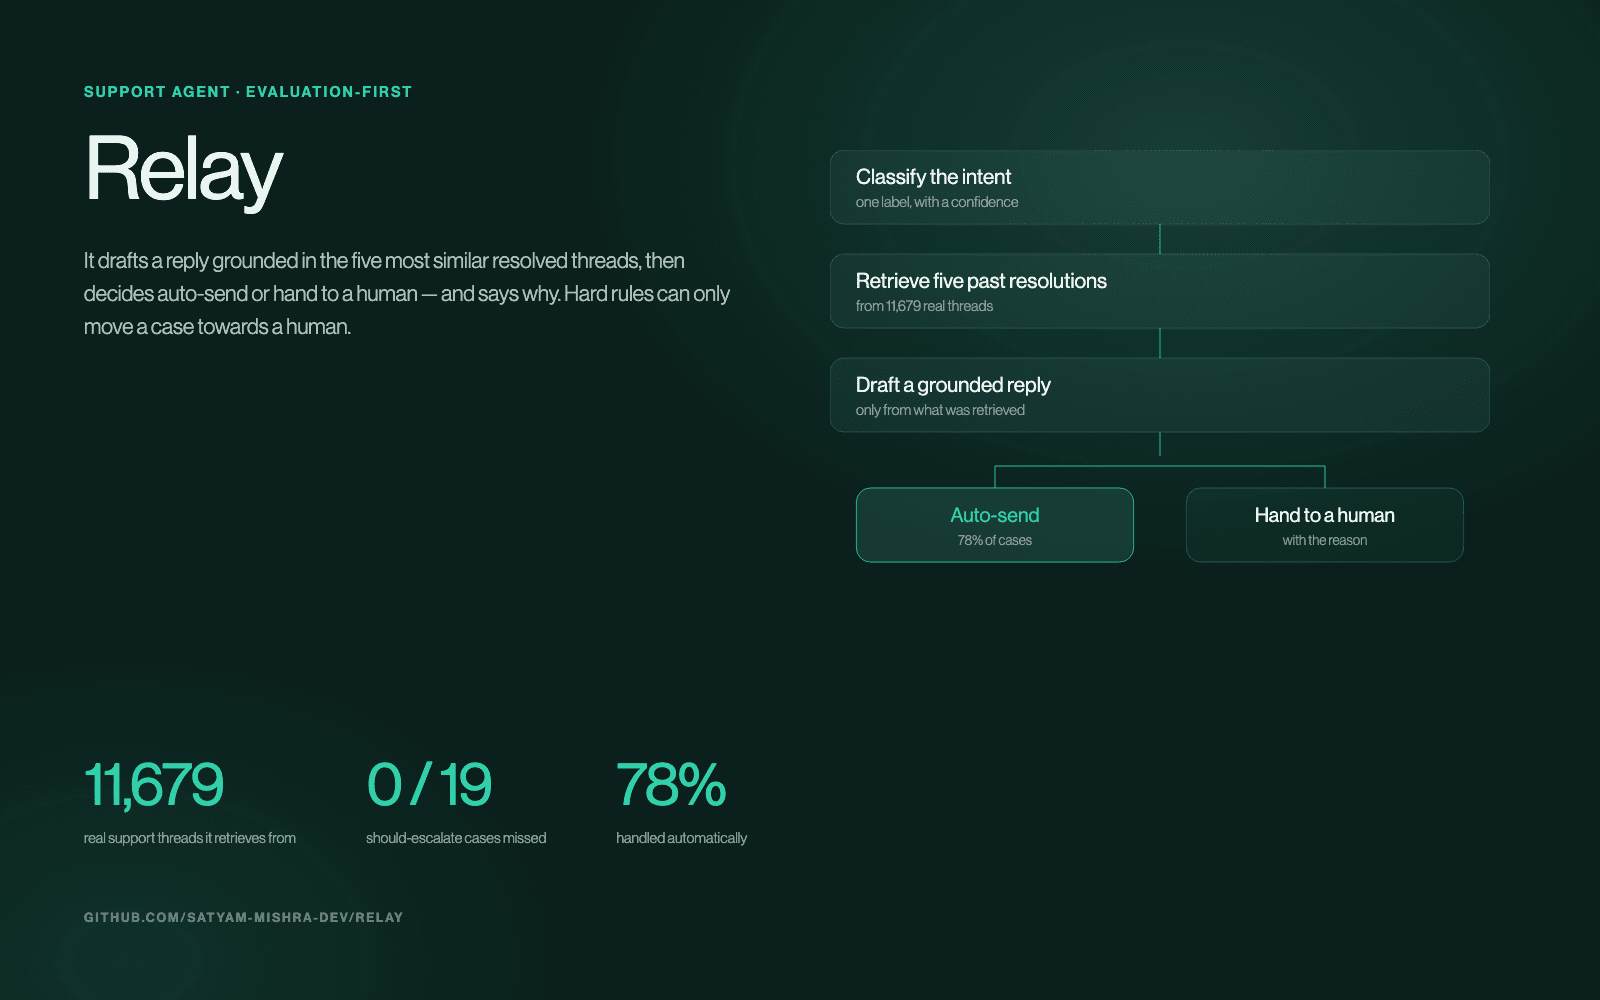
A customer support agent for a brand’s Twitter handle. It classifies what the customer wants, drafts a reply grounded in the five most similar resolved conversations out of 11,679 real threads, and then decides whether to send it automatically or hand it to a human, with the reason stated. Hard rules can only ever move a case towards a human, never away from one.
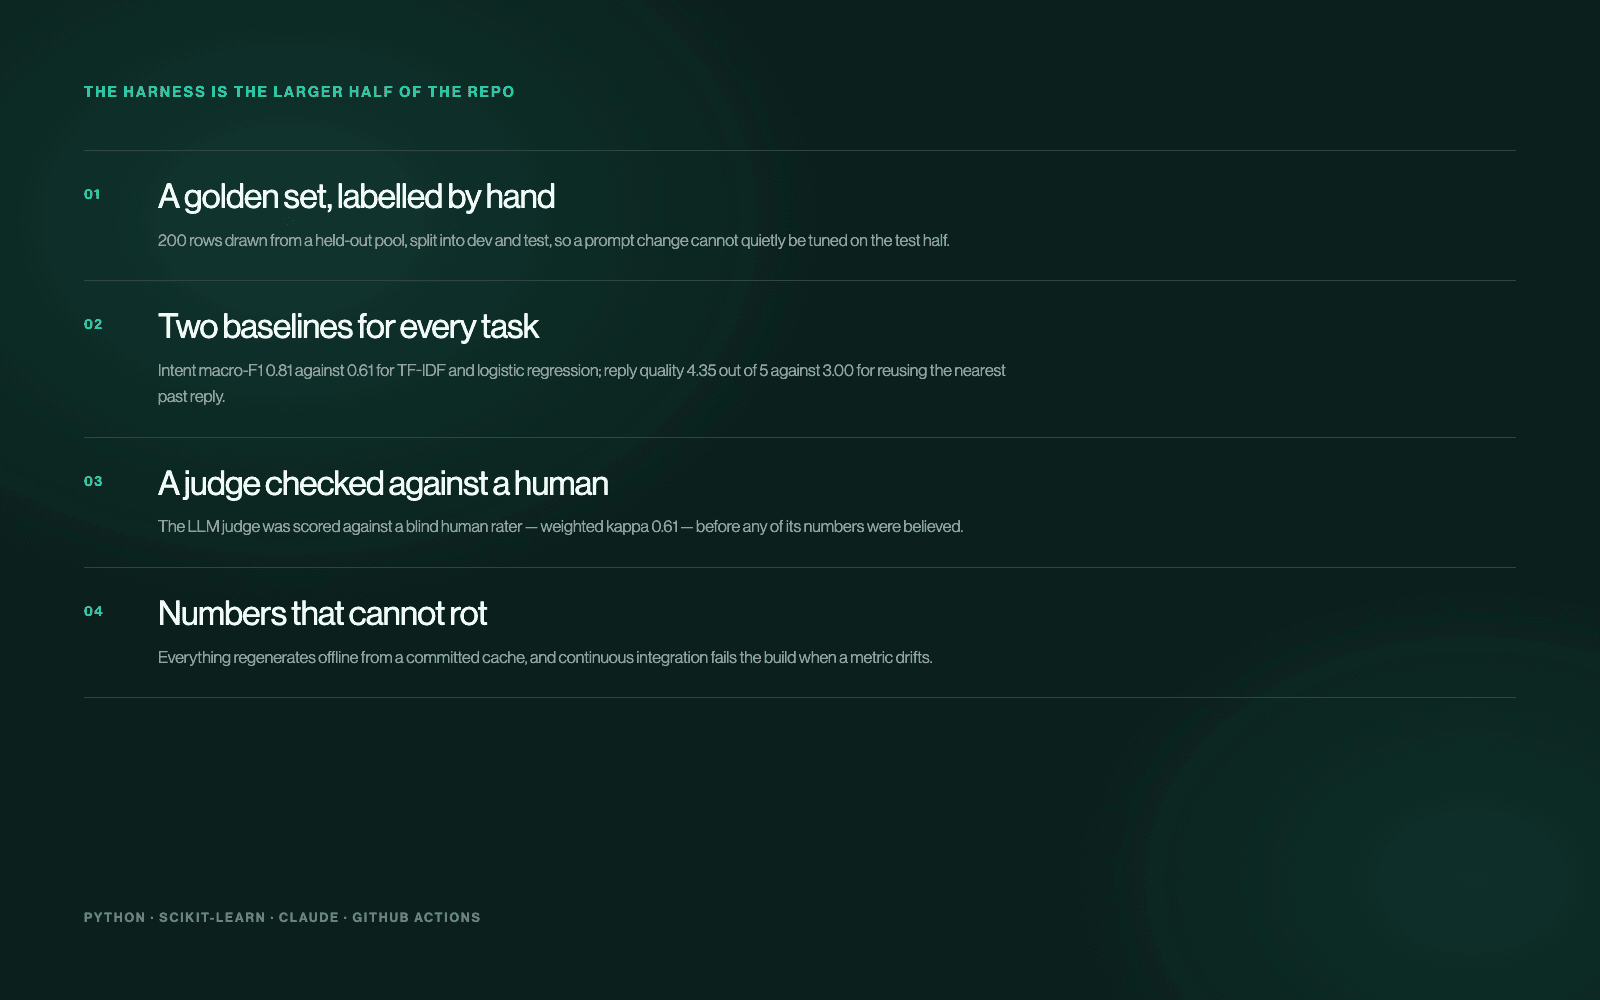
The evaluation harness is the larger half of the repository, because the agent is only as good as the evidence for it. A 200-row golden set hand-labelled from a held-out pool, a dev and test split, two baselines for every task, and an LLM judge whose scores were checked against a blind human rater (weighted kappa 0.61).
The headline numbers: none of the 19 cases that should have been escalated were auto-handled, at 78% automatic coverage; intent classification macro-F1 of 0.81 against 0.61 for a TF-IDF and logistic regression baseline; reply quality 4.35 out of 5 against 3.00 for simply reusing the nearest past reply. Every number regenerates offline from a committed cache, and continuous integration fails if a metric drifts.